
What if your API returns HTTP 200 but customers still can’t complete checkout? A basic health check may pass even when authentication, data validation, or a multi-step workflow is broken. Synthetic API monitoring can catch these failures by sending planned requests through important user journeys before real users report a problem.
That signal has limits. A failed synthetic check shows what the test couldn’t do, not necessarily why the application failed or how many users are affected. Production telemetry adds that context. Used together, synthetic checks validate defined workflows, while telemetry helps explain failures.
This guide explains how synthetic API checks work, which behaviours are worth testing, and how to set intervals and alert thresholds without creating noise. You’ll also learn how to distinguish monitor errors from application failures and route useful alerts into incident response and status communication. The goal is to catch meaningful problems early while keeping test results distinct from what’s happening across production traffic.
Key Takeaways
- Use synthetic API monitoring to test whether critical workflows behave as expected, not just whether an endpoint responds.
- Interpret each result in context: probe location, check cadence, timeout, and environment can affect what a failure means.
- Choose synthetic checks, uptime checks, and production telemetry based on the questions each signal can answer.
- Start with a small set of user-critical endpoints, clear ownership, and alert rules that reduce noise.
- Treat a failed check as an investigation signal. Confirm customer impact before sharing a public incident update.
What synthetic API monitoring tests, and what it cannot prove
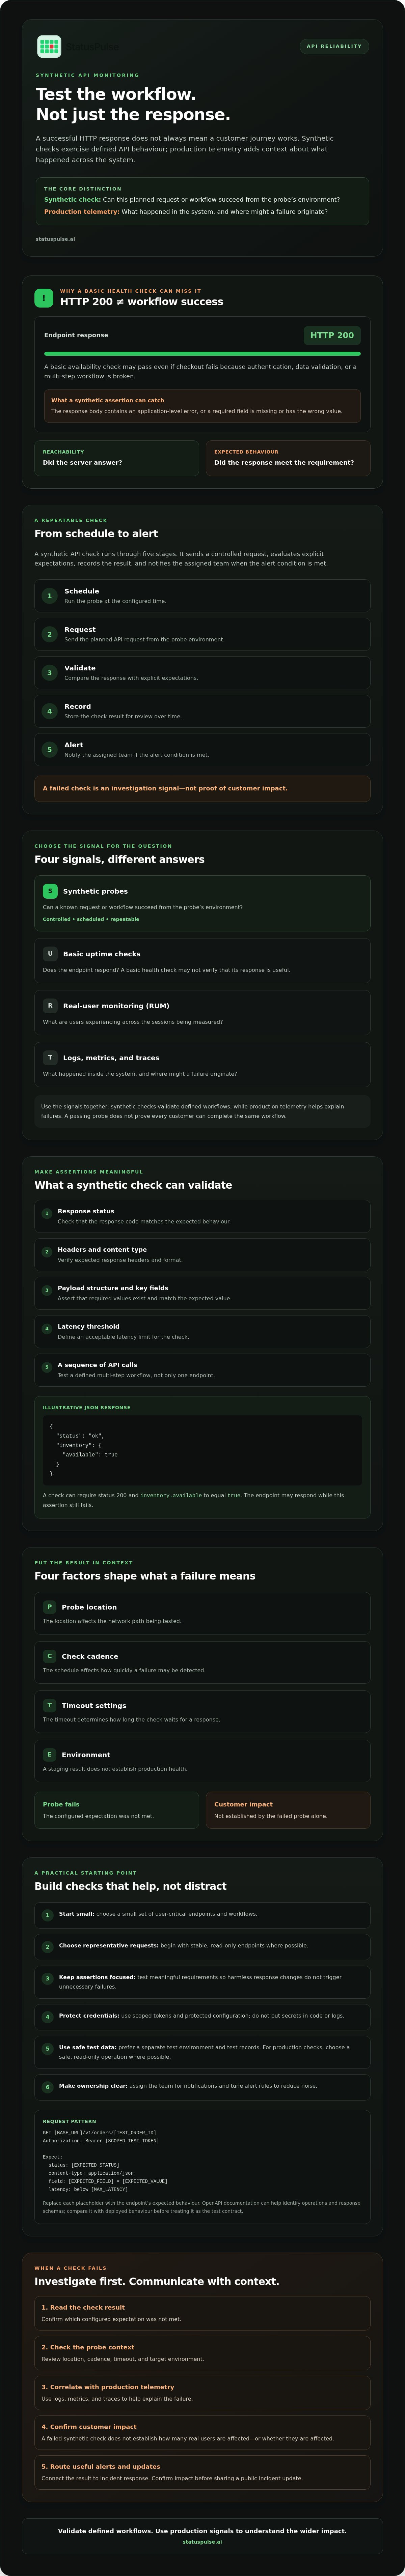
An endpoint returns HTTP 200, but checkout fails because the response omits the inventory field the client needs. A basic availability check may report success. Synthetic API monitoring looks beyond reachability by sending scheduled, controlled requests and checking whether the service behaves as expected.
A check can validate a response code, headers, payload values, or a sequence of API calls. It provides repeatable evidence about the path it tests. It cannot represent every user, network, device, or production condition, and it does not show by itself how many real users are affected.
How synthetic API checks differ from a basic health check
A basic health check often asks whether a service responds. A synthetic check can also verify whether the response is useful. For example, HTTP 200 may accompany an application-level error in the JSON body, or the response may lack a required field.
Example: validate a JSON field
{
  "status": "ok",
  "inventory": {
"available": true
  }
}
A check could require the response status to be 200 and inventory.available to equal true. If the field is missing or false, the check fails even though the endpoint responded. That distinction changes the question from “Did the server answer?” to “Did the expected behaviour work?”
Synthetic monitoring versus real-user monitoring and telemetry
Synthetic monitoring uses controlled probes to run a defined test repeatedly. Real-user monitoring (RUM) records aspects of actual user sessions, while logs capture events, metrics show aggregated measurements, and traces follow requests across services. Each signal answers a different question.
- Synthetic probes: Can a known request or workflow succeed from the probe’s environment?
- RUM: What are users experiencing across the sessions being measured?
- Logs, metrics, and traces: What happened inside the system, and where might a failure originate?
Synthetic results are repeatable, which helps teams detect regressions and compare outcomes over time. But a passing probe doesn’t prove every customer can complete the same workflow. A failing probe may reflect the probe’s network or configuration rather than an application fault. Correlate the result with production telemetry before drawing conclusions. For a broader view of API monitoring practices, read this API monitoring guide.
How a synthetic API check runs from request to alert
A synthetic API check follows five stages: schedule, request, validate, record, alert. A probe runs at the configured time, sends its request, compares the response with explicit expectations, and stores the result. If the alert condition is met, it notifies the assigned team. This repeatable sequence is the foundation of synthetic API monitoring.
A failed synthetic check means a configured expectation wasn’t met; it doesn’t, by itself, prove customer impact. Probe location affects the network path being tested. Cadence affects how quickly a failure may be detected, while timeout settings determine how long the check waits. The target environment matters too: a staging result doesn’t establish production health. IBM’s overview explains more about how synthetic monitoring works.
Design requests that test meaningful API behaviour
Begin with stable, representative read-only endpoints. Define assertions for the expected status code, response structure, essential fields, and an acceptable latency threshold. OpenAPI documentation can help identify operations and response schemas, but compare it with deployed behaviour before treating it as the test contract.
Illustrative request, with placeholders:
GET [BASE_URL]/v1/orders/[TEST_ORDER_ID]
Authorization: Bearer [SCOPED_TEST_TOKEN]

Expect:
  status: [EXPECTED_STATUS]
  content-type: application/json
  field: [EXPECTED_FIELD] = [EXPECTED_VALUE]
  latency: below [MAX_LATENCY]
Replace each bracketed value with the endpoint’s expected behaviour. Keep assertions focused on meaningful requirements, so harmless response changes don’t trigger unnecessary failures.
Handle authentication, test data, and dependencies safely
Use scoped credentials and store secrets in protected configuration, not in code or logs. Prefer a separate test environment and test records. If a check must target production, choose a safe, read-only operation where possible.
Document the dependencies exercised by each request. If an upstream identity provider or downstream service fails, the API response may fail too. Record that relationship so responders can distinguish an API defect from a dependency issue.
- Schedule: Set a cadence that balances detection needs with probe traffic.
- Request: Select the environment and location that fit the question you’re testing.
- Validate and record: Define assertions and retain useful diagnostic detail.
- Alert: Route meaningful failures to the service owner with enough context to investigate.
StatusPulse offers API monitoring, but API monitoring does not necessarily include synthetic checks. Review the API monitoring platform details and verify that the specific capability you need is supported.
Synthetic API monitoring compared with uptime checks and observability
Synthetic API monitoring adds a controlled behavioural test to your monitoring signals. It complements instrumentation rather than replacing traces, metrics, or logs. IBM’s overview of synthetic monitoring explains how planned requests can test services.
| Signal | Can detect | Can miss | Common use |
|---|---|---|---|
| Synthetic API check | Configured request, response, and workflow failures. | Conditions the test doesn’t represent, including user-specific issues. | Verify critical API behaviour from a defined probe. |
| Simple uptime check | Whether a host or endpoint responds. | Invalid payloads or broken application behaviour behind a successful response. | Track basic availability. |
| Production telemetry | Actual request patterns, internal errors, latency, and service dependencies, depending on instrumentation. | Issues that aren’t captured or instrumented. | Investigate what happened in live systems. |
Which API failures are synthetic checks suited to detect?
A configured check can detect an endpoint becoming unreachable, an authentication regression, a malformed response, or a failure in a selected workflow. Its coverage is limited to conditions represented by its requests and assertions. A read-only catalogue check, for example, won’t reveal a broken payment flow.
Rate limits, changing response data, and unstable dependencies can also produce misleading results. Keep assertions focused on stable behaviour, and identify external dependencies so responders can investigate the right component.
When should teams rely on another signal or tool?
Use production telemetry to investigate actual requests, internal behaviour, and distributed dependencies. Traces can show where requests fail across services, while logs and metrics add event detail and system-level context. Real-user signals are more useful when experience may vary by geography, device, or user-specific conditions.
A lightweight health check may be enough if you only need to know whether a service responds. An existing observability stack may also suffice if it already covers the behaviours and alerts your team needs. Add synthetic checks to fill meaningful gaps, not to duplicate signals. For availability fundamentals, see this uptime monitoring guide.
How to implement synthetic API monitoring without noisy alerts
Good synthetic API monitoring starts with a small set of checks that answer important questions. Choose user-critical endpoints, assign an owner to each check, and define what should happen when an expectation fails. Expand coverage only when the results help teams detect or diagnose a real risk.
A synthetic alert reports a failed test condition, not automatically a customer-impacting incident. Treat it as a prompt to investigate, then confirm scope and impact before escalating or communicating an outage.
Choose coverage and alert conditions deliberately
Prioritise endpoints by user impact, dependency importance, and recovery needs. For each check, record the service owner, escalation path, and planned maintenance windows so responders know who should act and when a failure may be expected.
Set the schedule according to the detection time your team needs, without generating unnecessary traffic. Base timeouts on expected service behaviour, not guesswork. Retries can filter transient probe errors, but too many may delay notification or hide intermittent failures. Consider alerting on persistent failures or failures across independent probe locations rather than on one isolated error.
Investigate a failed check before declaring an incident
Use a consistent review sequence. Repeat the check, then compare its result with independent signals such as uptime checks, application metrics, and logs. Inspect the request and response assertions, TLS status, DNS resolution, and relevant dependency health. This helps distinguish an application defect from a probe, network, credential, or dependency problem.
Keep known limitations beside the check definition. A test environment with stale data, a test credential near expiry, or a dependency that behaves differently under probe traffic can produce misleading results. Review these details when a check is added and after its first alert, then adjust the test or alert condition based on what responders learn.
- Select: Start with a few endpoints tied to important user tasks.
- Assign: Name an owner and document escalation and maintenance expectations.
- Tune: Set cadence, timeout, retry behaviour, and persistence or location criteria.
- Review: After the first alert, confirm the cause, usefulness, and next action.
Once a failure is verified, monitoring signals can support a clear incident workflow. Explore API monitoring and incident communication as part of that workflow, and verify any specific synthetic-check requirements with the provider.
Connect API monitoring to clear incident communication
A failed synthetic check is useful evidence, not a public incident announcement. Keep four steps distinct: detection, human confirmation, customer-impact assessment, and communication. This prevents a probe error or isolated test failure from being presented as a confirmed service disruption.
After detection, responders should repeat or cross-check the result and investigate alongside production telemetry. Then assess which service or workflow is affected, whether customers are experiencing the issue, and what action is underway. Only after that assessment should the team decide whether to publish an update.
Use monitoring evidence to support accurate status updates
A clear update gives customers verified information without overstating what the team knows. Include the affected service, confirmed impact, current action, and when customers can expect the next update. If the impact is still under investigation, say so plainly rather than treating the synthetic result as proof of widespread failure.
AI-assisted summaries can help organise incident details, but a person should review them before publication. Check that the summary reflects confirmed facts, avoids exposing sensitive diagnostic information, and doesn’t imply a resolution that hasn’t been verified. For more on structuring this process, see the incident communication architecture guide.
Evaluate a monitoring platform against your actual workflow
Choose tools based on what your team needs to detect and communicate. Check whether API monitoring, public status pages, and incident communication fit the existing response process. Confirm how alerts reach responders and who approves customer-facing updates. Don’t assume monitoring, incident confirmation, and publication should happen automatically as one step.
StatusPulse provides API and uptime monitoring, public status pages, and AI-assisted incident updates. These capabilities can support monitoring and customer communication, but they don’t confirm support for synthetic API checks. Verify that requirement directly before treating the platform as a synthetic monitoring provider.
Review StatusPulse monitoring and status pages if you’re assessing how monitoring evidence and customer communication could fit your workflow.
Build a monitoring strategy your team can trust
Synthetic API monitoring helps test whether defined requests and workflows behave as expected. It doesn’t prove every customer is unaffected, so pair check results with production telemetry and investigate before declaring an incident. Start with a few user-critical endpoints, clear ownership, and alert conditions that distinguish persistent failures from transient probe issues.
Detection is only part of the response. Confirm customer impact before publishing an update, and keep a human in the loop when preparing incident communication. The monitoring platform you choose should fit both your technical coverage and your team’s incident workflow.
StatusPulse combines API and uptime monitoring with public status pages. Its AI tools assist with incident updates and summaries. Verify whether synthetic checks are supported before selecting it for that specific capability.
Explore StatusPulse monitoring and status pages to see whether its monitoring and communication features fit your workflow. Clear checks, useful alerts, and thoughtful updates give your team a practical foundation for responding with confidence.
Frequently Asked Questions
What is synthetic API monitoring?
Synthetic API monitoring runs scheduled, controlled requests to check whether an API meets defined expectations. A check might verify a response code, required field, or selected workflow. It only tests what its requests and assertions cover, so it can’t represent every user’s experience.
How does synthetic API monitoring work?
A probe runs on a schedule, sends a configured request, checks the response, records the result, and alerts if a condition fails. The probe’s location, environment, timeout, and network path shape what the result means. A failure identifies a failed expectation, not necessarily its cause.
What is the difference between synthetic API monitoring and uptime monitoring?
Uptime monitoring typically checks whether a host or endpoint responds. A synthetic API check can also validate response content, authentication, or selected workflow behaviour. Use a basic uptime check for reachability; add behavioural assertions when you need to verify how an API responds.
Can synthetic API monitoring test authenticated endpoints?
Yes, provided the check supports the endpoint’s authentication method. Use scoped test credentials, store secrets securely, and keep them out of code and logs. Prefer read-only requests or isolated test data to avoid unintended changes, especially when checks run against production.
How often should an API synthetic check run?
Choose a cadence based on the endpoint’s importance, acceptable detection delay, and probe traffic. There’s no universal interval. Consider timeouts, retries, and rate limits too. Frequent checks may add load, while an overly slow schedule can delay detection.
Can synthetic API monitoring replace logs, metrics, and traces?
No. Synthetic checks test defined requests. Logs, metrics, and traces help investigate actual system behaviour and requests across dependencies, depending on instrumentation. Use synthetic results to spot a failure, then consult production telemetry to understand its cause and scope.
What causes false alerts in synthetic API monitoring?
Probe network or DNS issues, short timeouts, expired credentials, rate limits, changing data, and unstable dependencies can trigger misleading failures. Brittle assertions can also reject valid responses. Compare the result with another signal and inspect the request before declaring an incident.


